Ideas evolve.
The details stay.
Add an object. Change the light. Build on the edits that came before. Choose a scene and drag the divider to compare the base model with MT Forcing across successive turns.
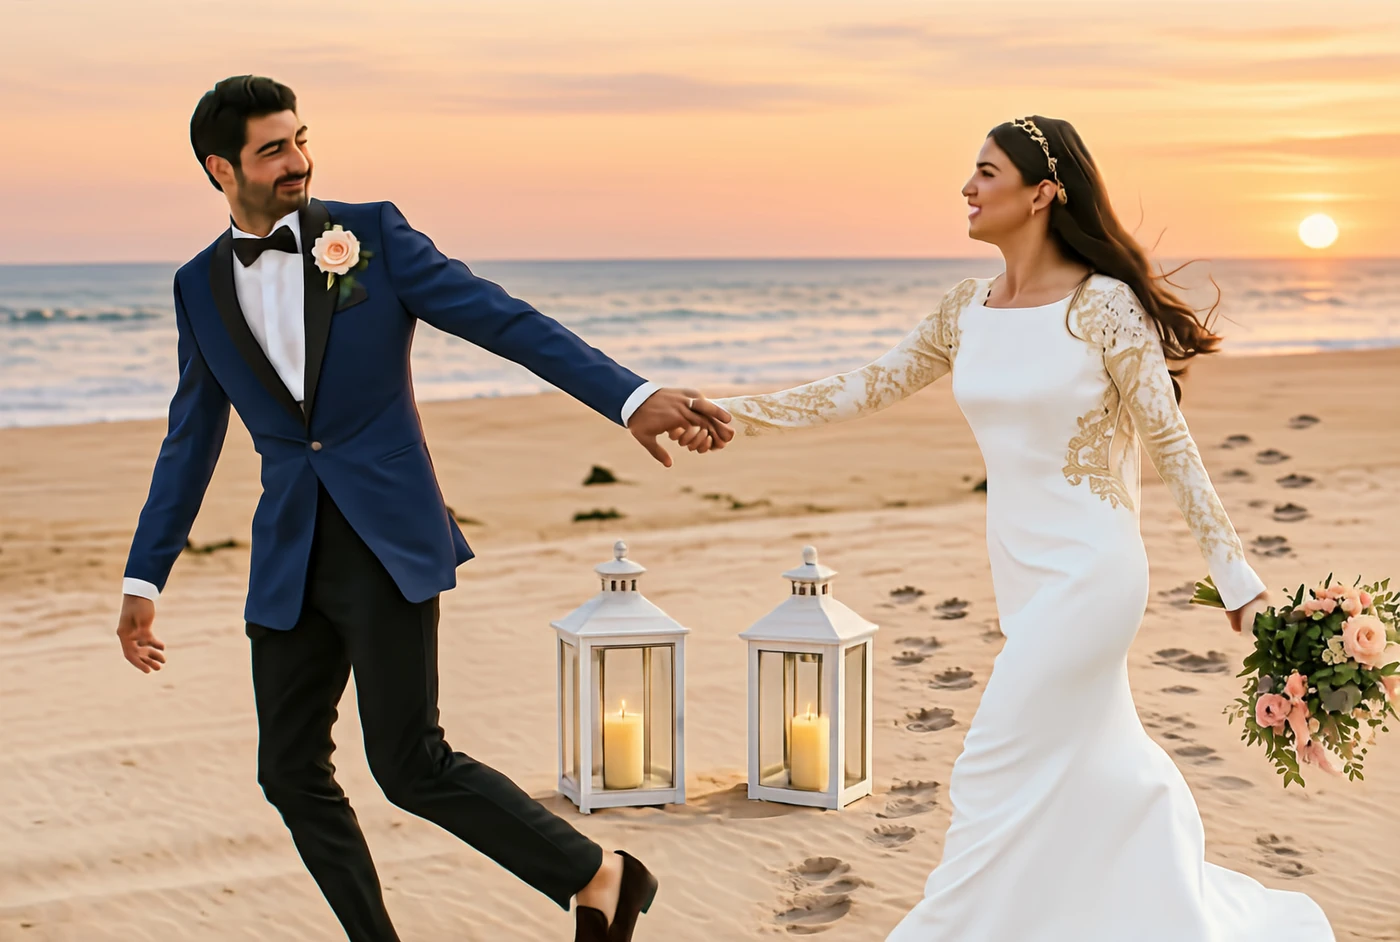
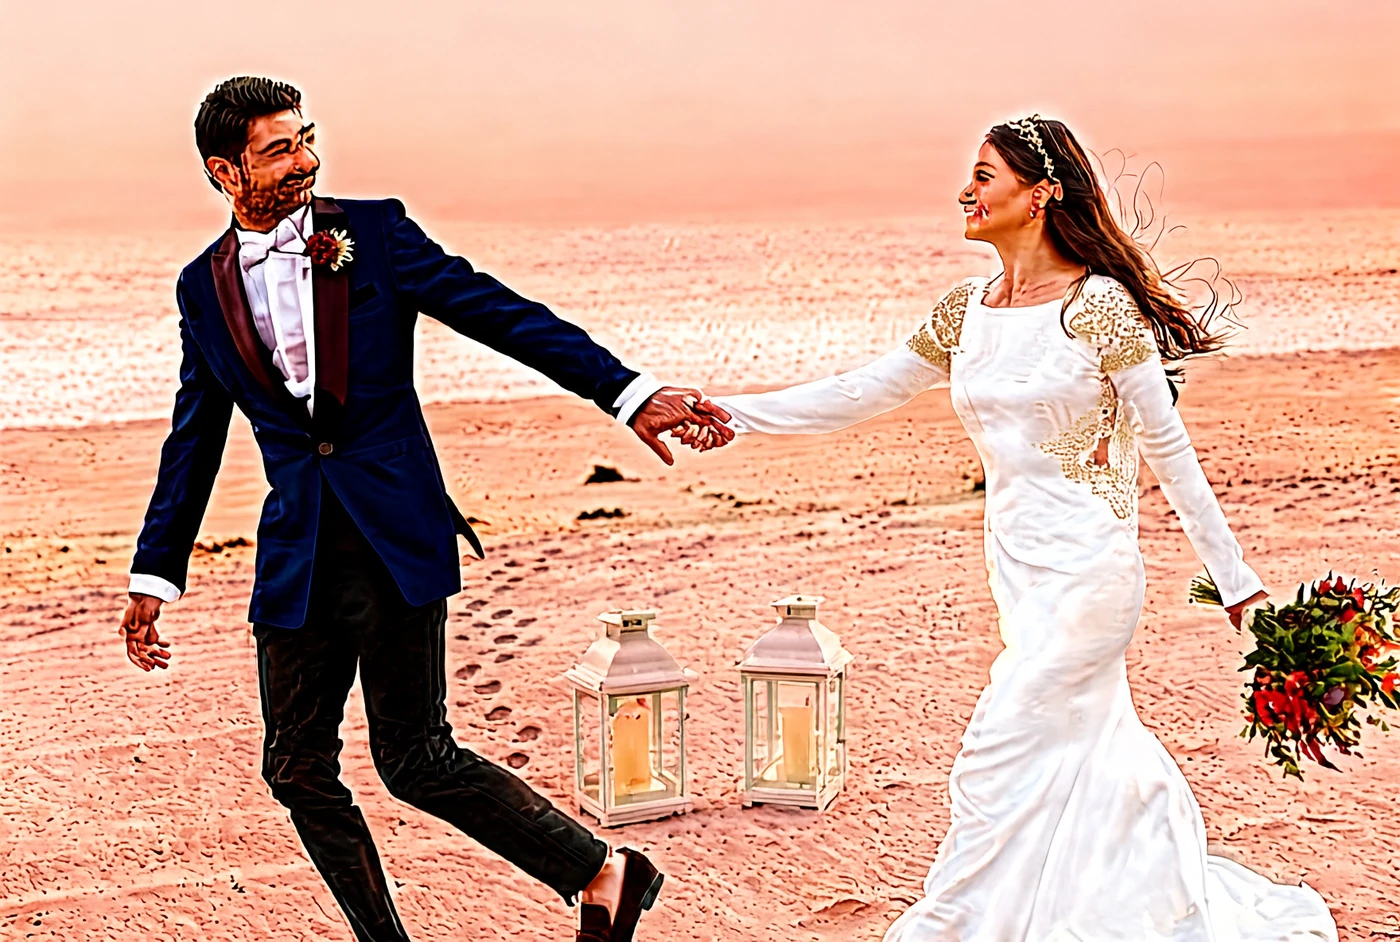
Restore champagne-gold embroidery on the sleeves, shoulder lace, and side cutout panels
Single-turn clarity.
Multi-turn consistency.
MT Forcing addresses two challenges: maintaining visual quality while editing self-generated histories, and preserving content relationships across turns.
A single-turn teacher.
Guidance at every turn.
The student edits its own generated history, one turn at a time. The teacher starts from the original image and applies the accumulated instructions in a single pass, providing distribution-level guidance without carrying errors across turns.
Goal: more stable visual quality Original image x₀
 x̂₁
 …
 x̂ₜ
Single-Turn DMD stabilizes visual quality. Teacher-Forcing Guidance supports consistency across turns. Both training signals guide the same student model.
Look beyond turn one.
Across 100 eight-turn sessions in MTEdit-Bench, MT Forcing improves sustained editing performance. The figures below show eight-turn averages for SenseNova-U1.5; explore the charts for per-turn results.
Content consistency
CC · Higher is better
View the full data table
Evaluation: eight-turn means weight all turns equally. IF and CC follow the benchmark’s failure-triggered scoring rule: turns after a failure receive zero. Pixel measures mean displacement between matched points; lower values indicate better spatial alignment. Interpret each metric separately.