I am a first-year Ph.D. student at MMLab, The Hong Kong University of Science and Technology (HKUST), jointly advised by Prof. Anyi Rao and Prof. Huamin Qu. I received my bachelor’s degree from Nanjing University (NJU), advised by Prof. Xun Cao. I interned at SenseTime guided by Lei Yang and Xiangyu Fan, and at the Beijing Academy of Artificial Intelligence (BAAI) and AIR, Tsinghua University guided by Prof. Hao Zhao. These internships gave me valuable research experience, and I am grateful to all my mentors and collaborators for their guidance and support!
My current research interests include visual content creation, image and video generation, and unified multimodal models. Feel free to reach out if you are interested in my research or would like to discuss potential collaborations!
🔥 News
- 2026: 🎉 1 paper accepted to ECCV 2026!
- 2026: 🎉 2 papers accepted to SIGGRAPH 2026 (including 1 ACM TOG paper)!
- 2026: 🎉 1 paper accepted to CVPR 2026 as a Highlight!
- 2026: 🎉 2 papers accepted to ICLR 2026!
📝 Selected Papers
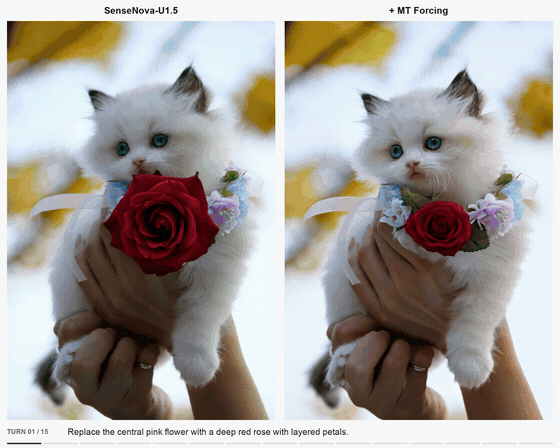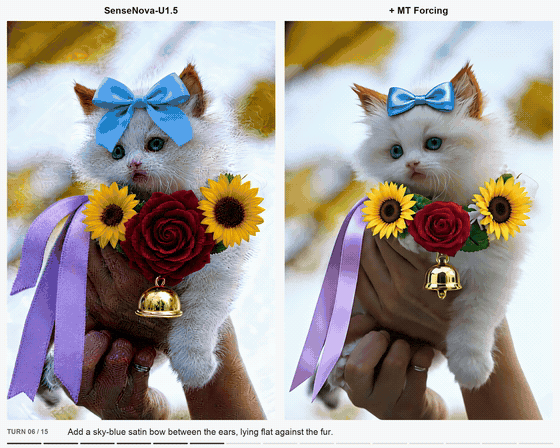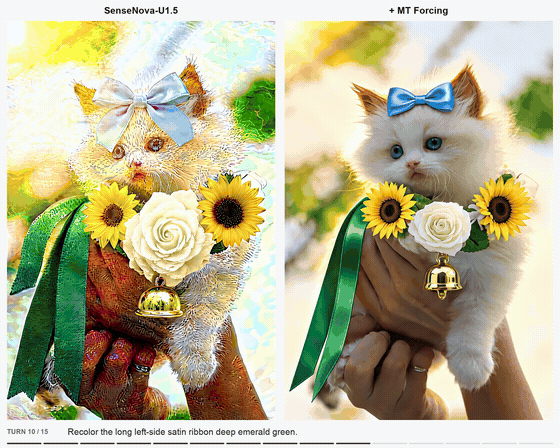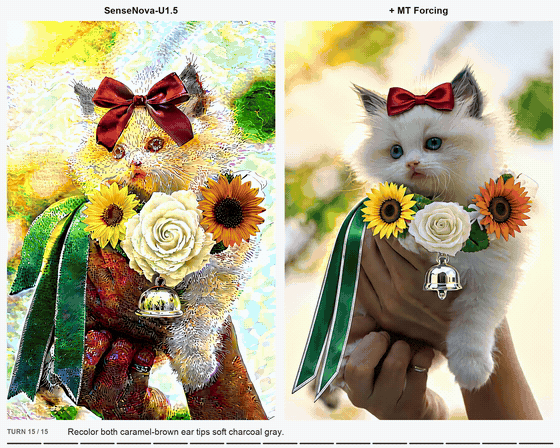
MT Forcing: Towards Stable and Consistent Multi-Turn Image Editing with Autoregressive Diffusion
Houyuan Chen*, Fanzhou Wang*, Xiangyu Fan, Zesong Qiu, Yukun Wei, Songlin Yang, Zhitao Yang, Lvmin Zhang, Pei Yang, Hao Zhao, Dahua Lin, Lei Yang, Anyi Rao

- A training framework that improves visual quality and content consistency for multi-turn image editing, where models iteratively build on their own outputs.
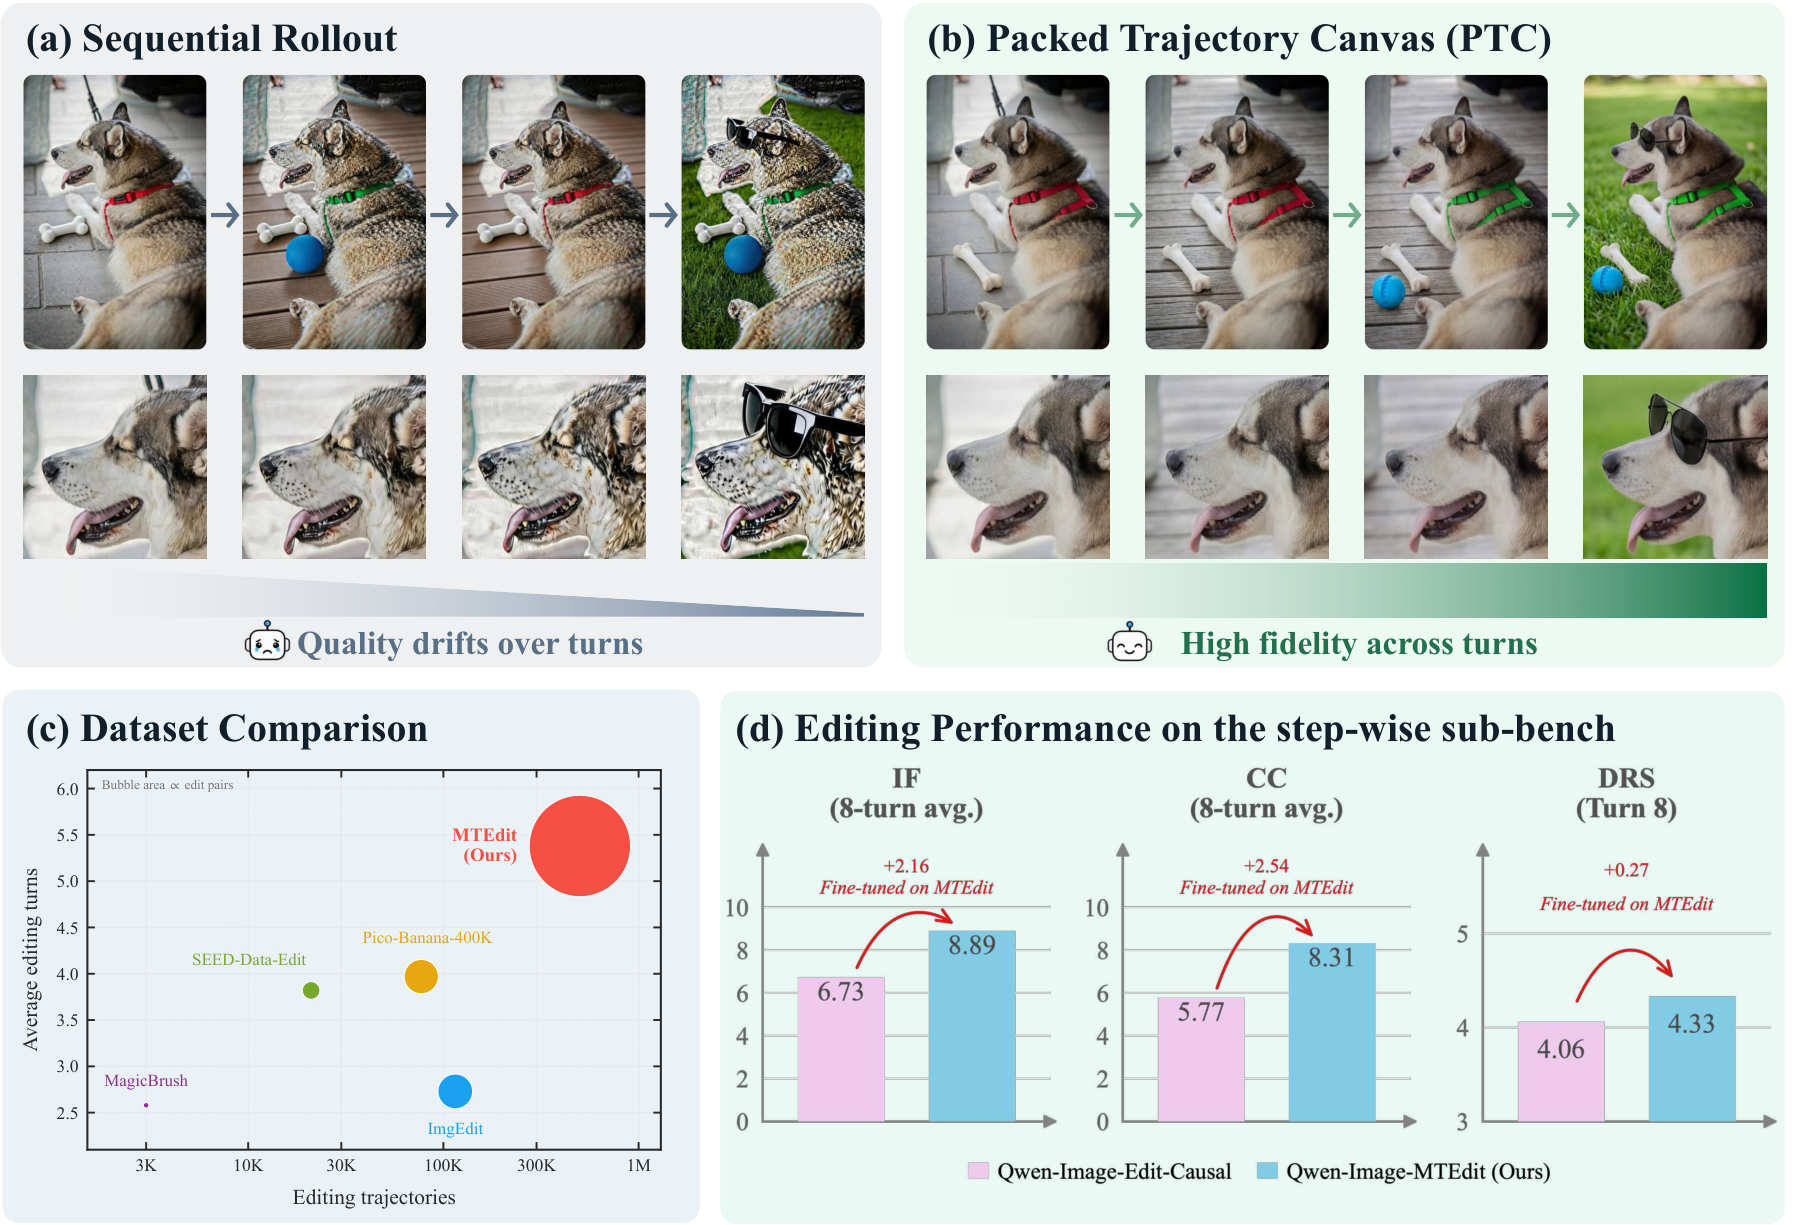
MTEdit: Packed Trajectories Beat Rollouts for Multi-Turn Image Editing
Houyuan Chen*, Fanzhou Wang*, Xiangyu Fan, Songlin Yang, Zhitao Yang, Lvmin Zhang, Pei Yang, Hao Zhao, Dahua Lin, Lei Yang, Anyi Rao
- MTEdit uses packed trajectory canvases to construct 500K multi-turn image editing trajectories, alongside MTEdit-Bench and Qwen-Image-MTEdit for evaluating and improving multi-turn editing.
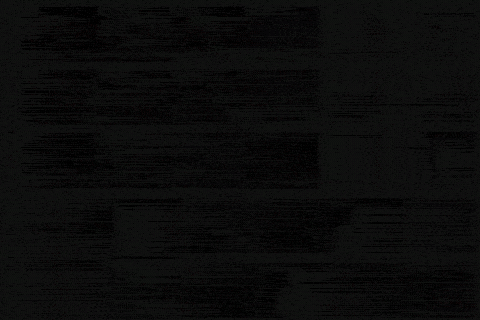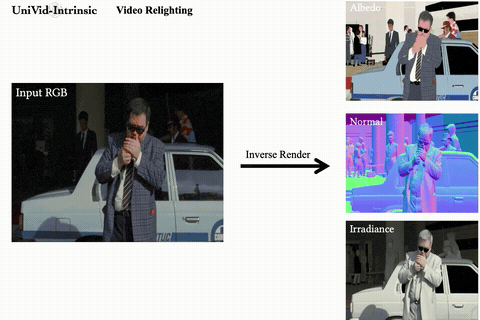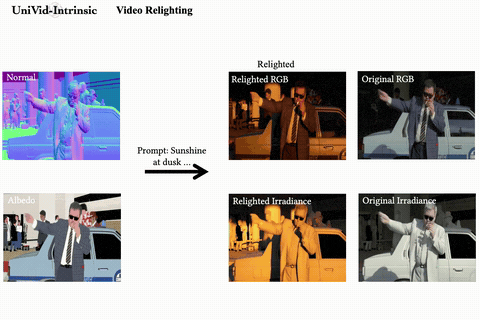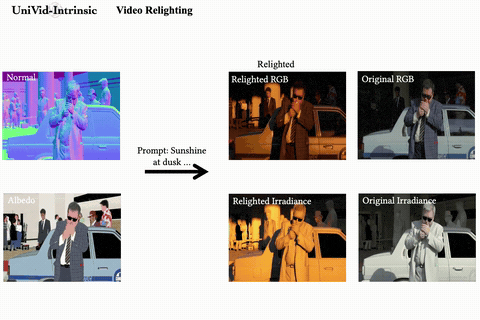
UniVidX: A Unified Multimodal Framework for Versatile Video Generation via Diffusion Priors
Houyuan Chen, Hong Li, Xianghao Kong, Tianrui Zhu, Shaocong Xu, Weiqing Xiao, Yuwei Guo, Chongjie Ye, Lvmin Zhang, Hao Zhao, Anyi Rao

- A unified framework that uses video diffusion priors for generation across RGB, intrinsic maps, and alpha layers, supporting tasks including relighting, decomposition, and matting.
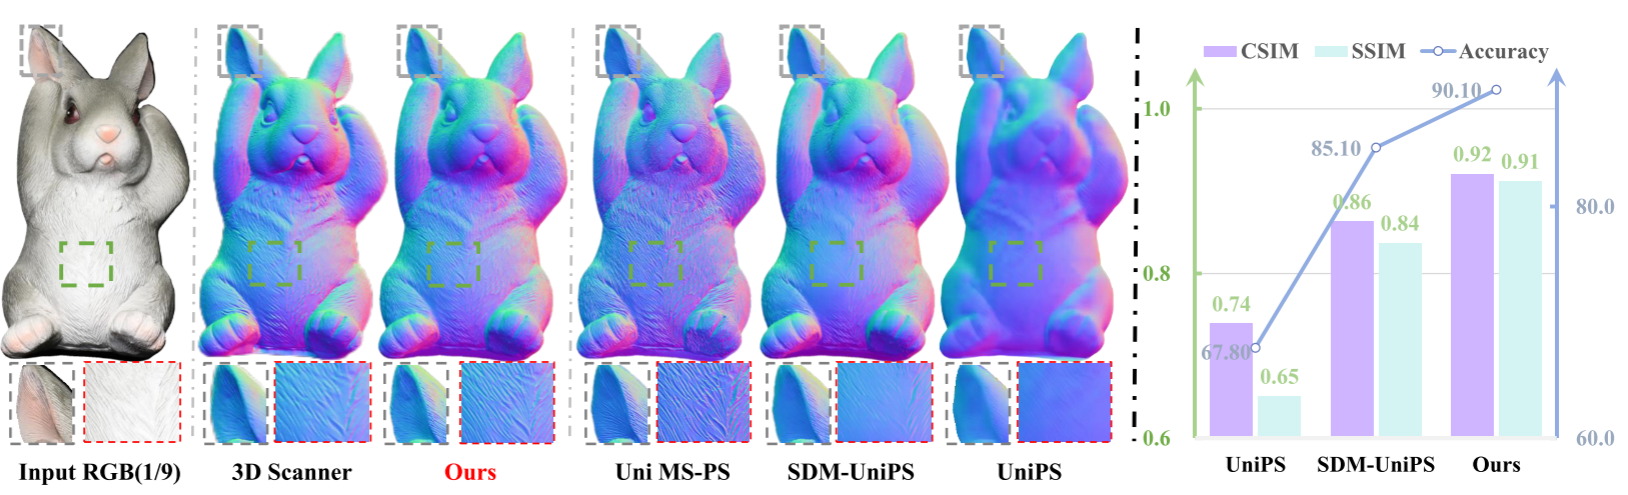
Light of Normals: Unified Feature Representation for Universal Photometric Stereo
Houyuan Chen*, Hong Li*, Chongjie Ye, Zhaoxi Chen, Bohan Li, Shaocong Xu, Xianda Guo, Xuhui Liu, Yikai Wang, Baochang Zhang, Satoshi Ikehata, Boxin Shi, Anyi Rao, Hao Zhao

- Decoupling lighting and geometry for detailed surface normal estimation under arbitrary, unknown illumination, with the PS-Verse training dataset.
- Relit-LiVE: Relight Video by Jointly Learning Environment Video, Weiqing Xiao*, Hong Li*, Xiuyu Yang*, Houyuan Chen, Wenyi Li, Tianqi Liu, Shaocong Xu, Chongjie Ye, Hao Zhao, Beibei Wang, SIGGRAPH 2026.
- Monocular Avatar Reconstruction via Cascaded Diffusion Priors and UV-Space Differentiable Shading, Hong Li*, Minqi Meng*, Yanjun Liang, Chongjie Ye, Houyuan Chen, Weiqing Xiao, Xianda Guo, Guojun Lei, Xuhui Liu, Chaojie Yang, Yanlun Peng, Hao Zhao, Baochang Zhang, ECCV 2026.
- NeAR: Coupled Neural Asset-Renderer Stack, Hong Li*, Chongjie Ye*, Houyuan Chen, Weiqing Xiao, Ziyang Yan, Lixing Xiao, Zhaoxi Chen, Jianfeng Xiang, Shaocong Xu, Xuhui Liu, Yikai Wang, Baochang Zhang, Xiaoguang Han, Jiaolong Yang, Hao Zhao, CVPR 2026 (Highlight).
- Post-Training Quantization for Video Matting, Tianrui Zhu, Houyuan Chen, Ruihao Gong, Michele Magno, Haotong Qin, Kai Zhang, ICLR 2026.
🎓 Education
- 2026 - Present, Ph.D. Student, MMLab, The Hong Kong University of Science and Technology (HKUST)
- Current Research Directions: Visual Content Creation, Image and Video Generation, Unified Multimodal Models
- Supervisors: Prof. Anyi Rao, Prof. Huamin Qu
- 2022 - 2026, Bachelor’s Degree in EE, Nanjing University (NJU)
- Ranking: 1st / 77
- Supervisor: Prof. Xun Cao
💻 Internships
- SenseTime: Guided by Lei Yang and Xiangyu Fan.
- Beijing Academy of Artificial Intelligence (BAAI) and AIR, Tsinghua University: Guided by Prof. Hao Zhao.
🎖 Awards
- National Scholarship
- China Mobile Scholarship
- Some High-Value Scholarships at Nanjing University
🕴️ Services
- Organizer of the CVEU Workshop at SIGGRAPH 2025, SIGGRAPH 2026, and SIGGRAPH Asia 2026.
- Conference Reviewer for CVPR, ECCV, ICLR, and SIGGRAPH Asia.
💻 Open Source
- Awesome-Relight
: A curated collection of relighting papers, datasets, benchmarks, demos, and tools.
🎤 Talks
- June 18, 2026: UniVidX: 视觉智能时代的一小步, TechBeat.